AI Image Generation Lab · Live
Stop guessing which
AI image tool actually delivers.
We run every generator through the same fixed prompts, keep the first output, and score every result at full resolution. No re-rolls, no cherry-picking — just the evidence, published in full.
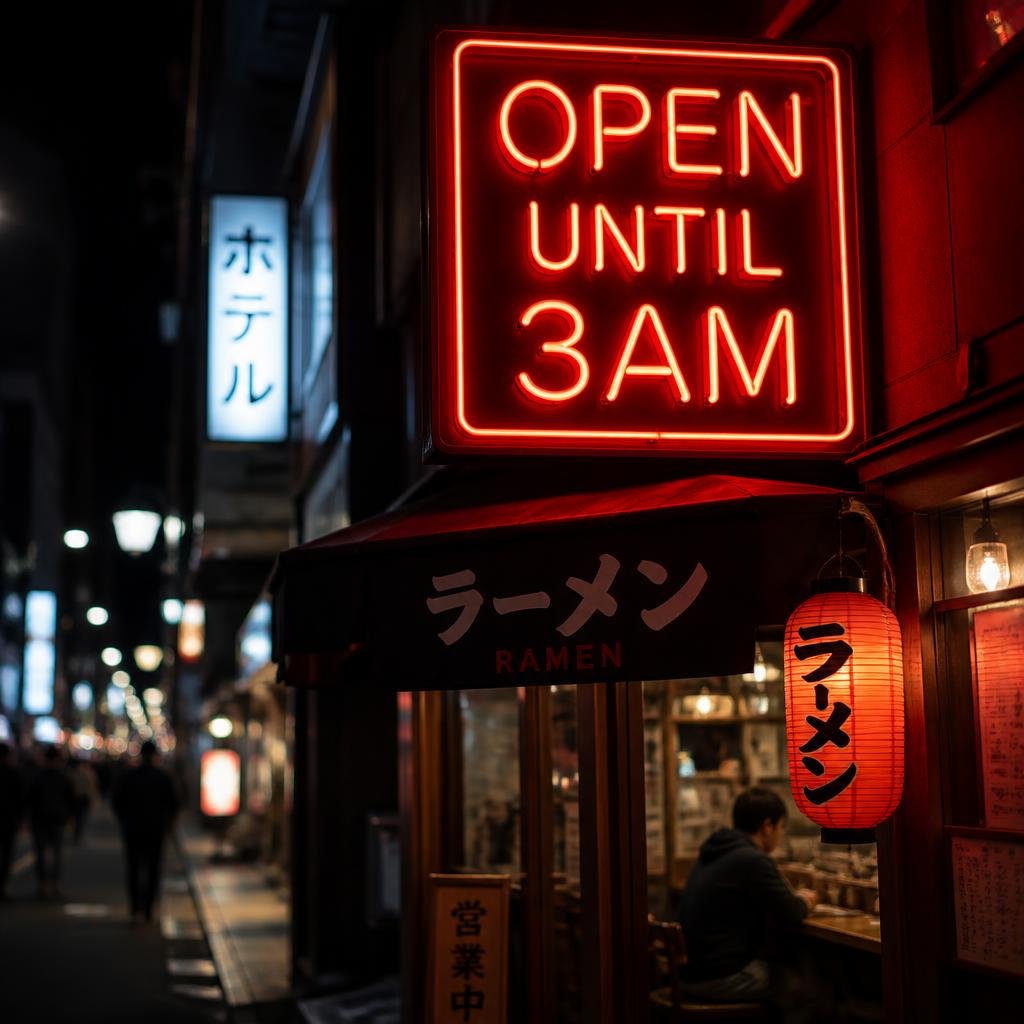 Winner
perfectly ✓
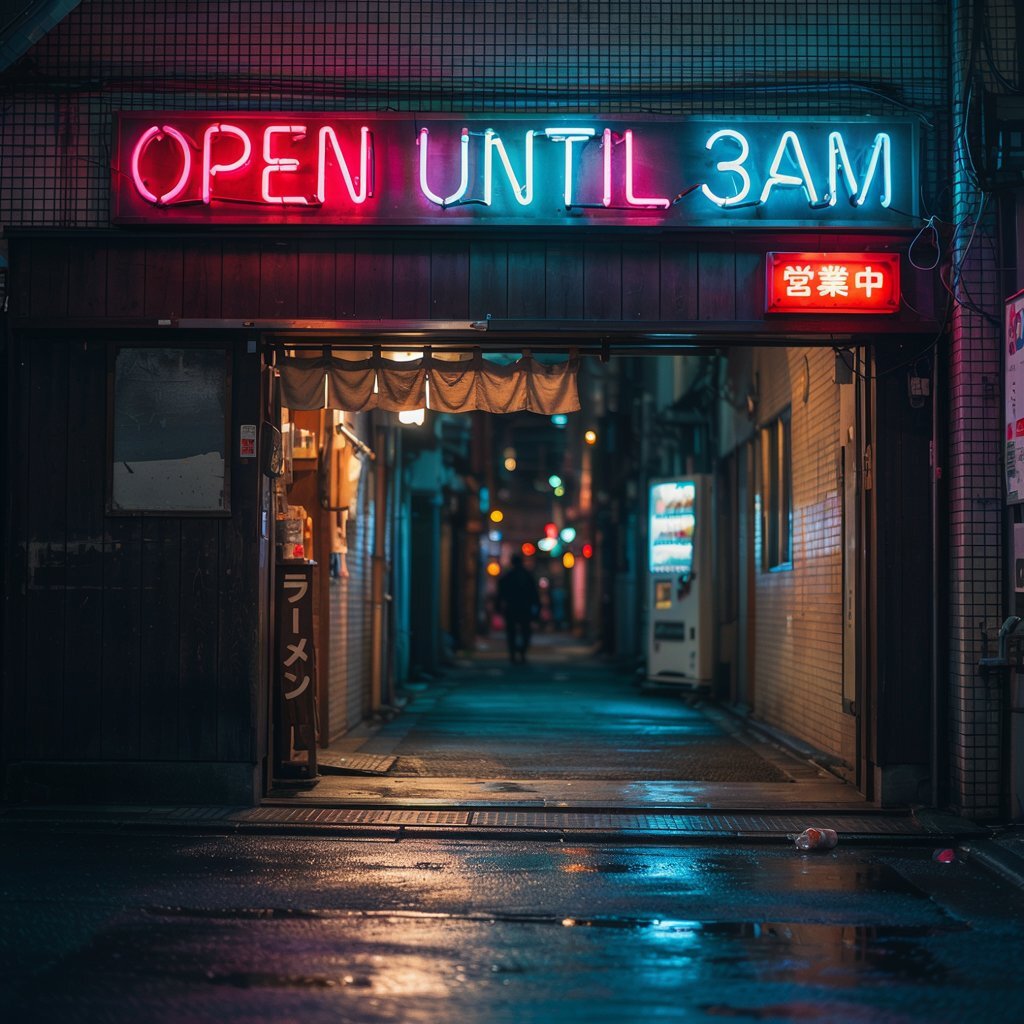
letters ✓
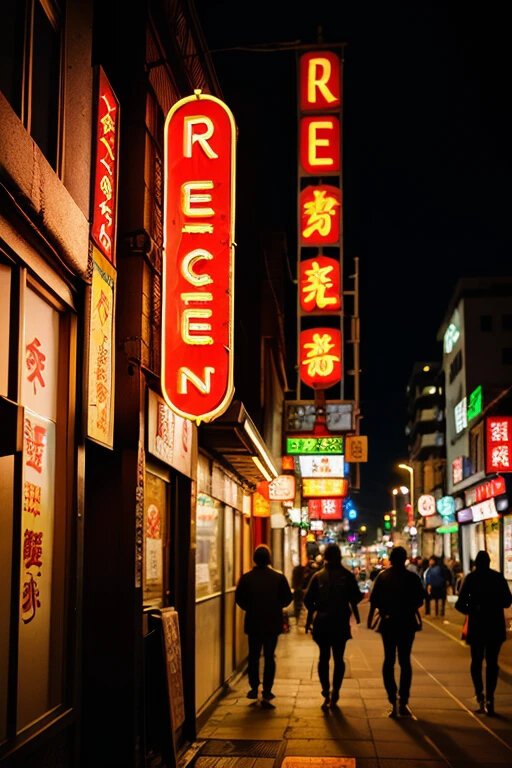
“RECEN” ✗
The labs
Each lab takes one category of AI tool and puts it through its own fixed, public benchmark, its own prompts, its own leaderboard. One is live now; more are in the works.
AI Image Generation Lab
Ten text-to-image tools, nine identical prompts, first output kept and scored on the same rubric. Every image published, the wins and the failures.
Enter the lab →Ranked by overall score, the mean of all nine images. Green is strong, amber middling, red a real weakness.
| # | Tool | Overall | Text | Photo | Hands | Product | Anime | Adhere |
|---|---|---|---|---|---|---|---|---|
| 1 | GPT Image 2 |
9.4 | 9.8 | 9.5 | 9.0 | 10.0 | 9.0 | 9.2 |
| 2 | 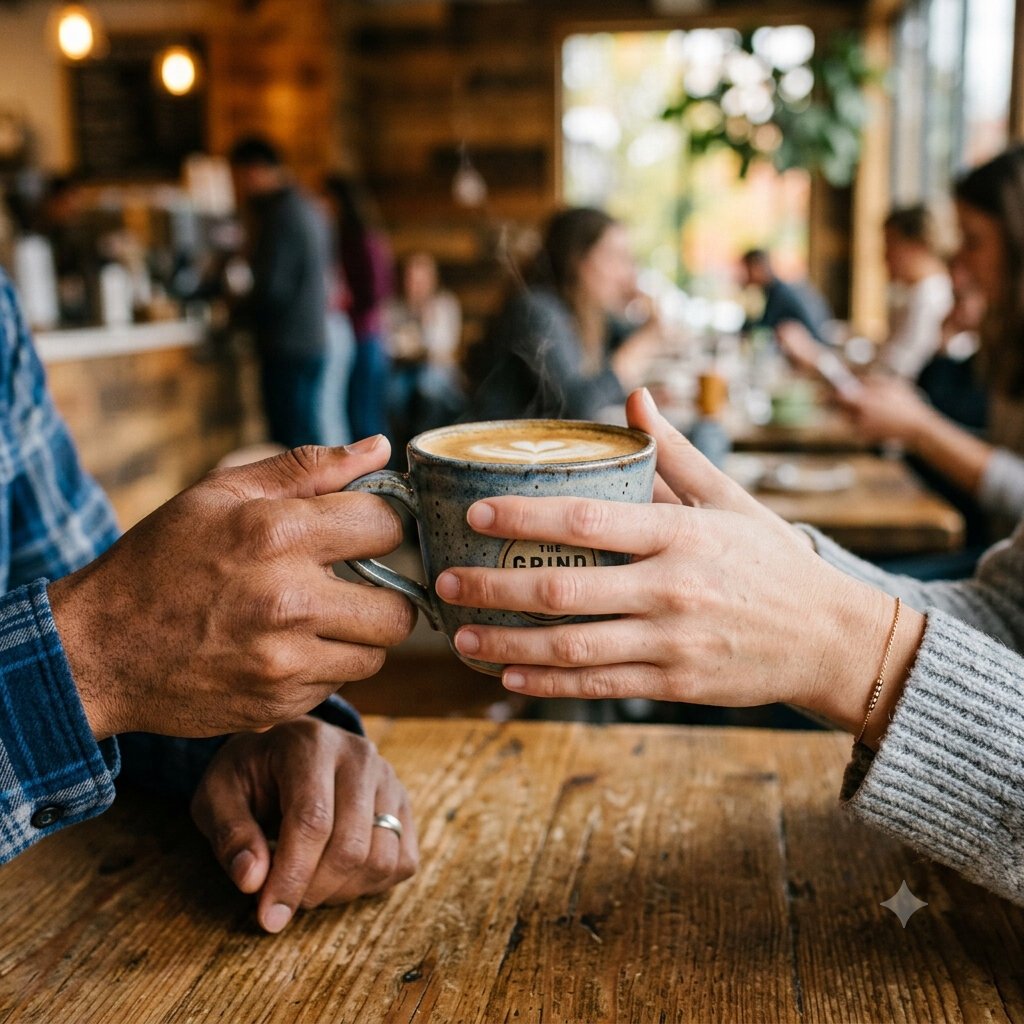 Nano Banana 2 |
9.4 | 9.0 | 9.2 | 9.7 | 10.0 | 9.3 | 9.5 |
| 3 | 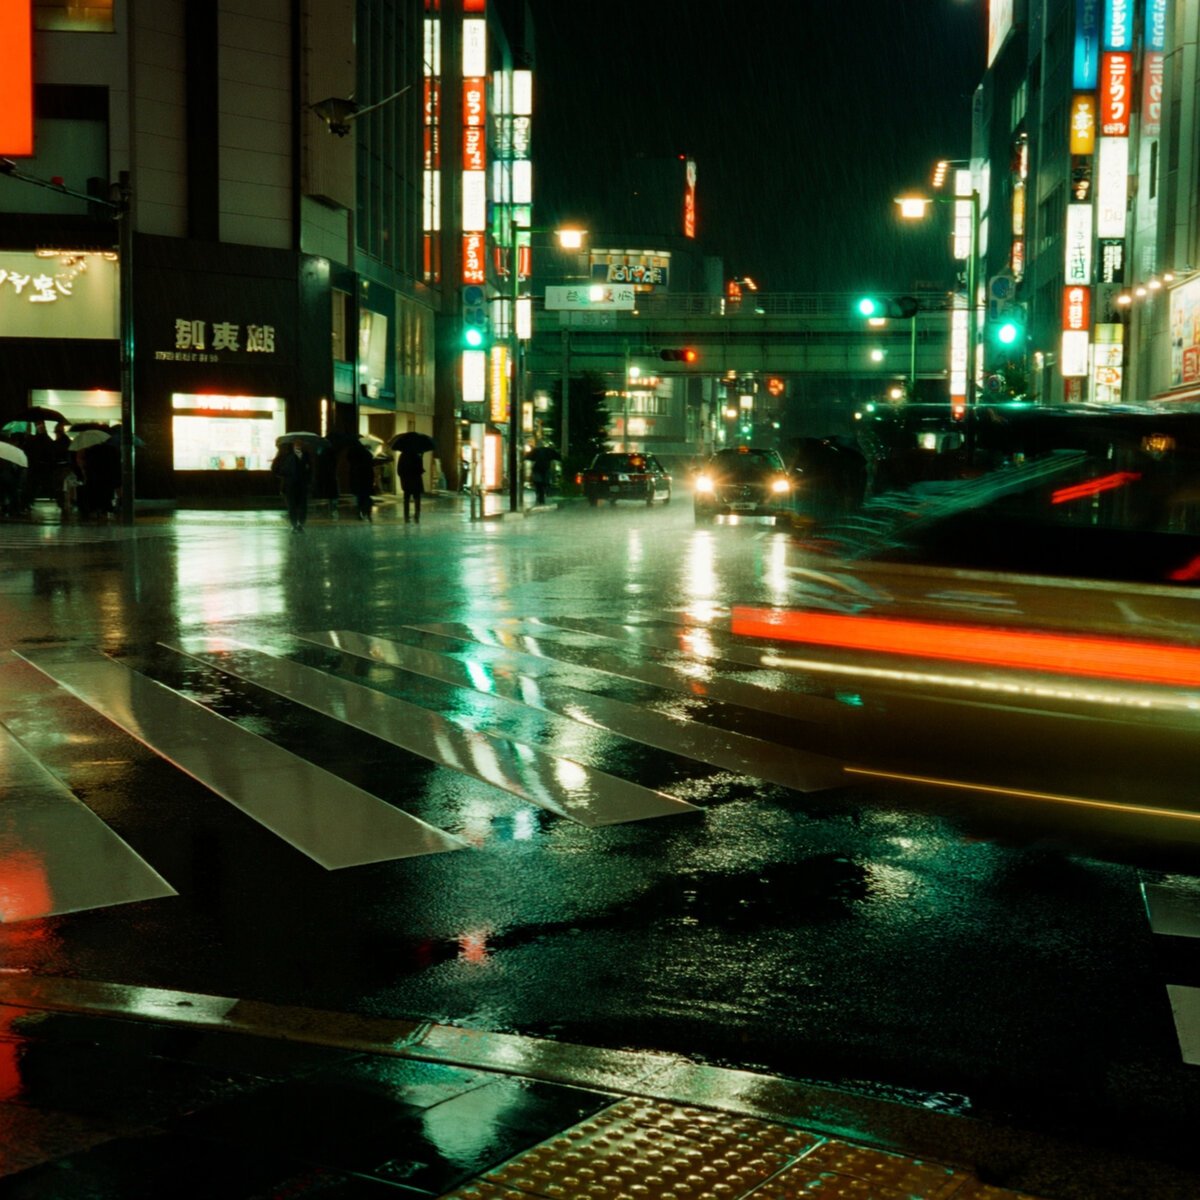 Imagine Art |
9.1 | 8.7 | 9.3 | 8.7 | 9.7 | 8.7 | 9.3 |
The overall leader is not always the right pick. Here is the top scorer in three key categories. Compare every tool, prompt by prompt →
Best for text9.8GPT Image 2
Text winnerPoint it at a sign, a label, or a logo and the words come out right. The only tool that reliably spells.
Read the full review →Best for hands & people9.7Nano Banana 2
Hands winnerThe only tool to nail a two-person cup exchange with correct fingers on both hands. Free, too.
Read the full review →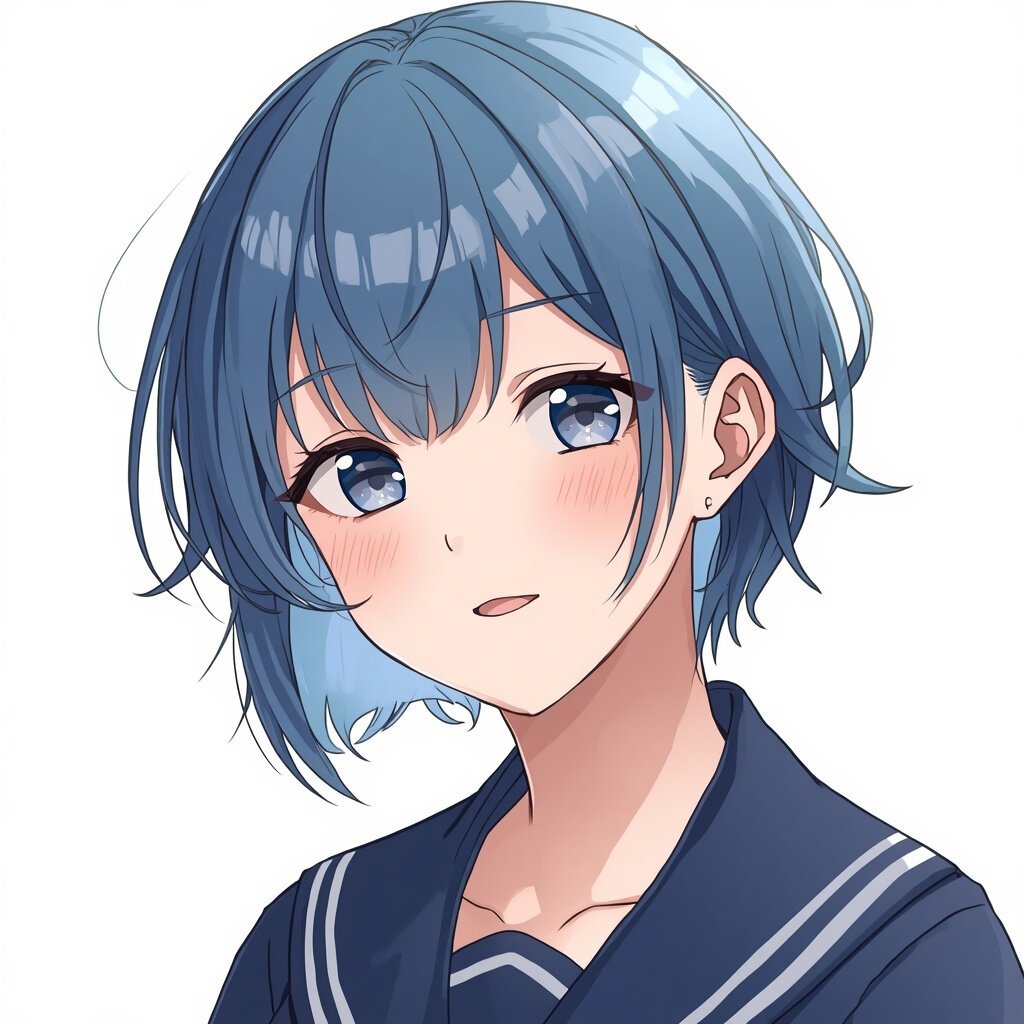 Best for anime9.3
Leonardo AI
Anime winnerA genuine cel-shaded illustration with clean lines and detailed eyes, not a photo wearing a wig.
Read the full review →Our testing method, and why it's fair
Most best-of lists rank tools the author never opened, using stock screenshots and vibes. We do the opposite, and the method is deliberately strict so the scores mean something.
Within each lab, every tool gets the identical set of prompts, pasted verbatim. We use default settings and keep the very first output, with no re-rolls and no picking the best of a batch. The moment you curate results, a benchmark becomes an opinion, so we don't.
We sell nothing on this list, which means there's no commercial reason to rank one tool over another. The scores are the scores.
One fixed prompt set per lab
Each lab uses its own set of identical prompts, given to every tool verbatim and designed to expose specific failure modes. The exact prompts live on each lab.
First output kept
Default settings, no re-rolls, no cherry-picking. The first result the tool returns is the one that gets scored.
Scored on a fixed rubric
Every result is scored on the same axes at full resolution, where artefacts actually show, then averaged. Each lab publishes its exact rubric.
No sponsorship, nothing for sale
We don't sell the tools we rank, so placement can't be bought. Outbound links go to each tool's official site, and none of them are affiliate links.
Category guides
Best free AI image generators
Eight free tiers ranked on benchmark scores, with daily limits, watermarks and commercial rights all tracked.
Read the guide →Most realistic AI image generators
All ten ranked on photorealism, plus the five tells that still give an AI image away.
Read the guide →Best for text inside images
Which tools can actually spell. All ten ranked on neon signage and product packaging.
Read the guide →All guides
Every category guide and tool review in one place, including our Pica AI and MeiGen AI write-ups.
Read the guide →More: Prompt seen promptsMeiGen AI promptsPica AI reviewGetimg.ai reviewDreamina review
Quick answers
What is Pipgen?
Pipgen is an AI tool testing lab. We take one category of AI tool at a time, put every tool through the same fixed, public benchmark, and publish the real results, the wins and the failures. Our first lab covers AI image generators; more are on the way, each with its own prompts and leaderboard.
How do you test and score tools?
Within each lab, every tool gets an identical set of prompts on default settings, and we keep the very first output with no re-rolls or cherry-picking. Each result is scored on the same fixed rubric at full resolution, then averaged into an overall score. Each lab publishes its exact prompts and rubric.
Why should I trust these rankings?
Because you can see the work. We publish every raw output behind every score, so you can judge for yourself rather than taking our word for it. We also sell none of the tools we rank, so placement can't be bought and the scores can't be influenced by a vendor.
Do you make money from this?
Outbound links go to each tool's official site and are not affiliate links. Nothing on any leaderboard is sponsored or paid for. The scores are the scores.